 measure
How to Track Your Brand's Visibility in Perplexity (2026)
Perplexity shows its sources on every answer, which makes it the clearest window into why an AI engine cites who it cites. Here is how to use that.
- Perplexity shows the live web sources behind almost every answer, which in our experience makes it the most transparent major AI engine to track and the easiest to learn from.
- That transparency plus a lower cost per query is why many tools can run Perplexity daily, so it can double as an early-warning signal for shifts across the wider AI search landscape.
- To read it well, track a fixed set of your buyers' real questions, then study the cited domains to see exactly why a rival gets named instead of you.
- Perplexity is search-first, so it reacts faster to your web footprint than ChatGPT does; the way to win is to be present in the domains it already cites for your questions.
Why Perplexity is the easiest engine to track
Perplexity was built as an answer engine first and a chatbot second. Ask it almost anything and it runs a live web search, reads the top results, and writes a short answer with numbered footnotes pointing straight back to the pages it used. Those citations sit inline on nearly every response, so you do not have to guess where an answer came from. You can see the exact domains, in order, that Perplexity trusted to build its reply.
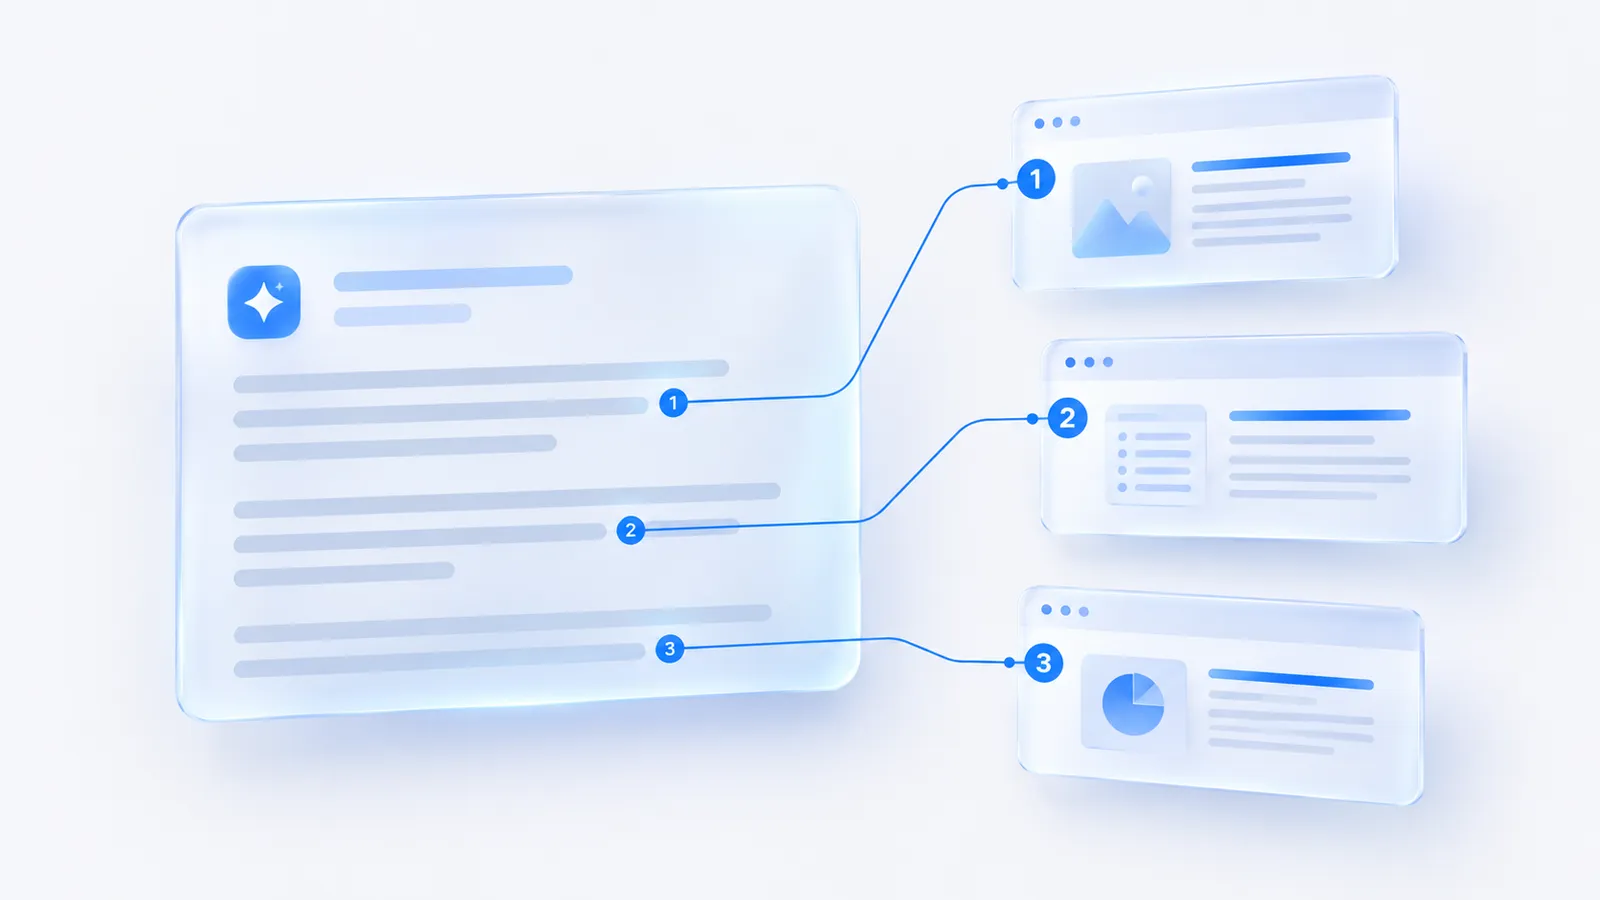
In our experience, no other major engine is this consistently open by default. ChatGPT and Gemini sometimes surface links, but the reasoning behind a given sentence is often opaque. Perplexity puts its working on the page. If you want to understand how AI engines decide which brands to recommend, it is the clearest window you have. For a fuller definition of what a citation is and why it matters, see our glossary entry on LLM citations.
Why it is your clearest early-warning signal
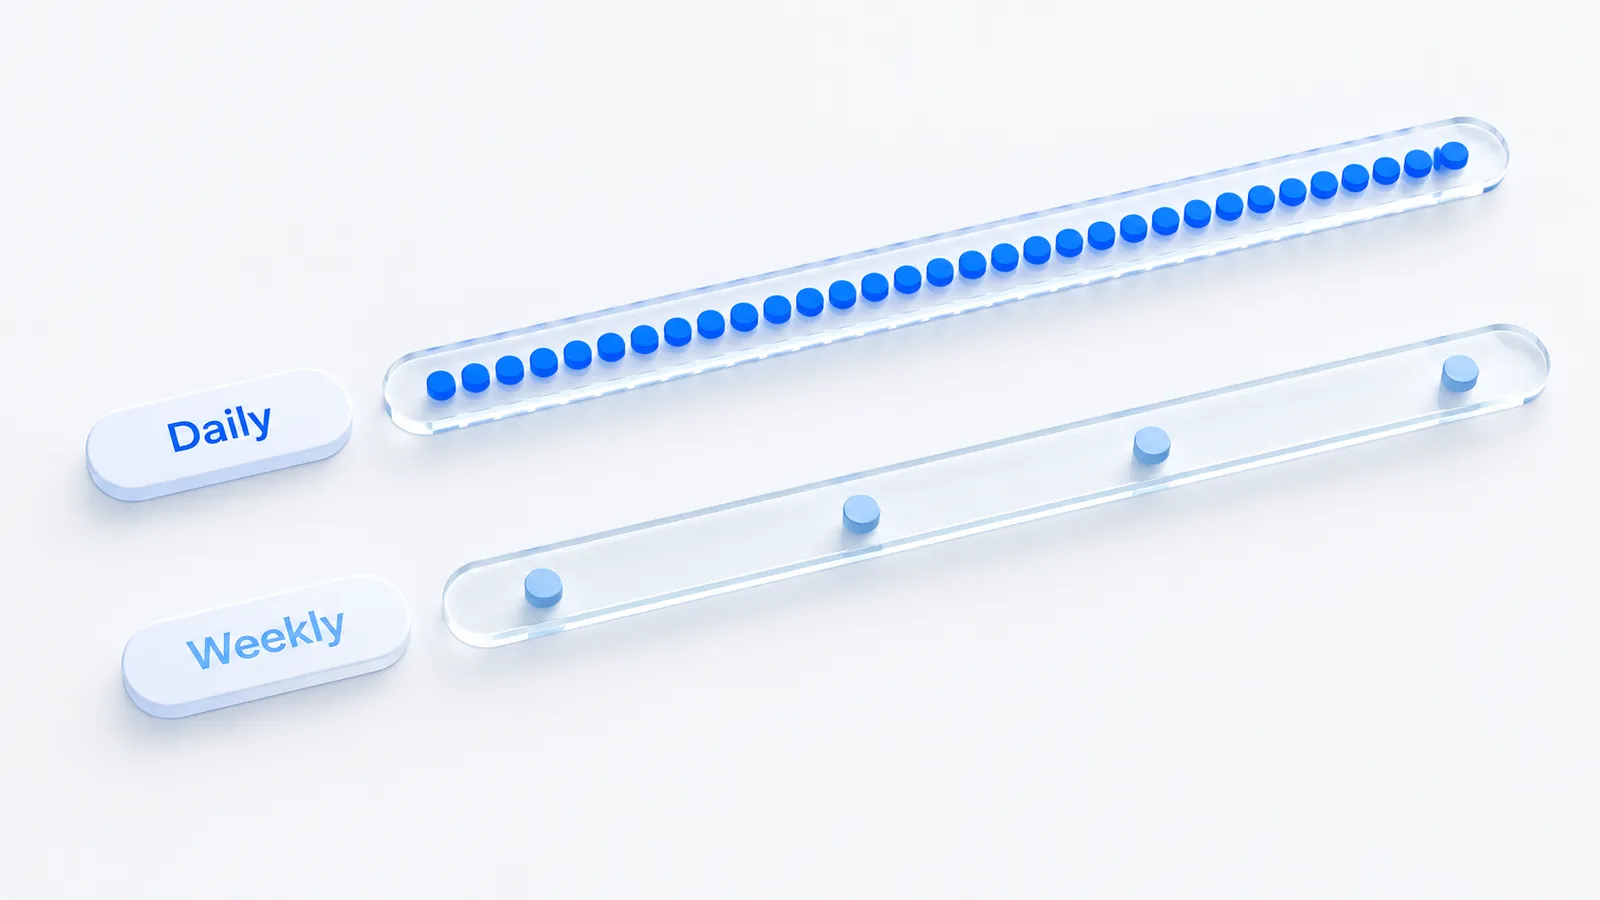
Transparency is only half the reason to lead with Perplexity. The other half is cost and cadence. Because a Perplexity query is cheaper to run than one against the heavier reasoning models, many tracking tools can afford to run it every day, where the more expensive engines are sampled less often on a schedule that scales with your plan. Daily data means you notice a change within a day or two rather than at the end of a monthly cycle.
That speed makes Perplexity a useful proxy for the wider field. Because it reads the live web, a shift in who it cites usually reflects a real change in what is published and linked about your category, and that same change often reaches the other engines later, though not always and not on a fixed timetable. If a competitor suddenly starts winning citations in Perplexity, treat it as an early warning that the same movement may be coming to ChatGPT, Gemini and Google AI Overviews. You get to react before the slower engines catch up.
Daily Perplexity tracking is not the same as daily tracking of every engine. Be wary of any tool that implies it checks ChatGPT, Gemini, Claude and Google AI Overviews every day on every plan. The expensive engines are sampled on a cadence, and that is fine. Perplexity is the one you can watch continuously, so use it as your fast lane and read the others as the slower confirmation.
Which prompts to track, and how to read the sources
The value of Perplexity data depends entirely on the questions you feed it. Track the prompts your buyers actually type when they are close to a decision, not vanity phrases that name your brand for you.
- Category questions. "Best [category] tools for [use case]" and "top alternatives to [competitor]". These are where a short list of brands gets named, and where being absent costs you the most.
- Comparison questions. "[Your brand] vs [rival]" and "is [your brand] worth it". Perplexity will pull from review sites, forums and comparison pages, so you see which third parties shape the verdict.
- Problem questions. "How do I [solve the problem your product solves]". These catch buyers earlier, before they know your category exists, and reveal which publishers own the top of the funnel.
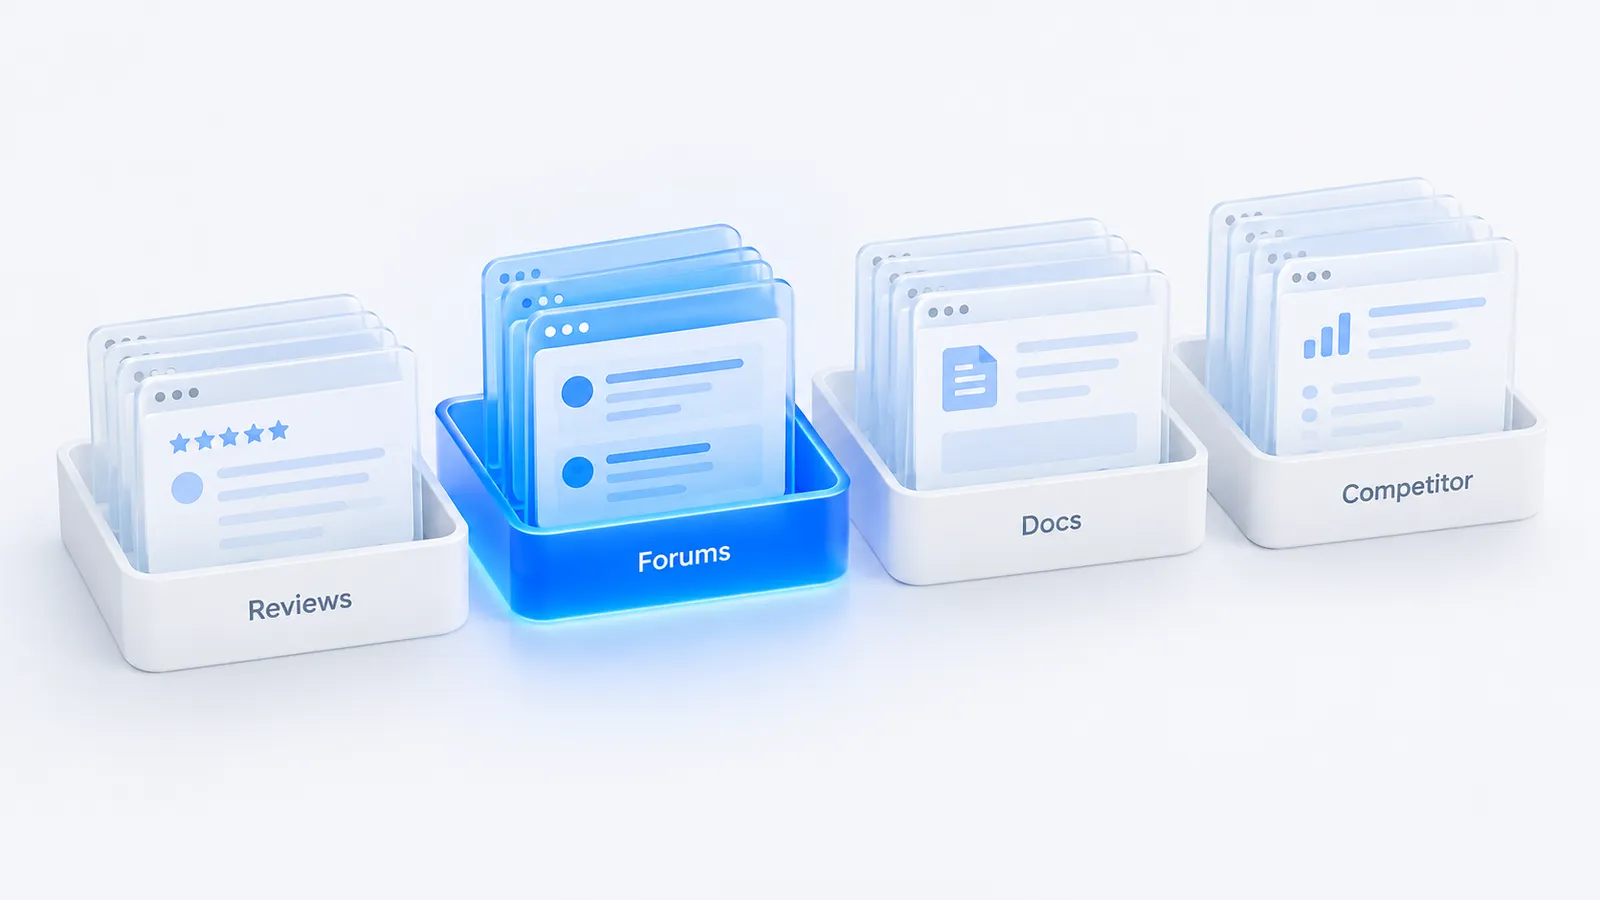
Once you have a fixed set, the real work is reading the cited sources, not just the yes-or-no of whether you were named. For each answer, look at the numbered footnotes and ask three things. Which domains got cited? Which of your rivals is named, and which source is the one carrying that mention? And is the winning page a review roundup, a documentation page, a forum thread, or the competitor's own site? The pattern tells you exactly why the rival wins. If three of the five sources behind a "best tools" answer are the same review site and you are not on it, you have found your next task.
Run each question more than once, too. Perplexity's answers vary between runs, so a single phrasing under-samples. Several phrasings aggregated over time turn noise into a trend you can trust.
Worked example: a 20-minute source audit
Here is the audit in practice. The brand and numbers are hypothetical, to show the method rather than report a result. A bookkeeping app picks five buyer questions and runs each twice in Perplexity, giving ten answers and, at roughly four to six footnotes each, around 50 citations to tally.
- Log every cited domain. One row per footnote: question, run, domain, page type (review roundup, forum thread, documentation, competitor site, news), and whether the brand is named on that page.
- Count by domain. Suppose one accounting review site is cited in 7 of the 10 answers and a single forum thread in 4. Those two pages shape most of what Perplexity says about the category.
- Check presence. The brand is listed on neither page. The rival named in 8 of 10 answers is on both. That one fact explains most of the visibility gap.
- Assign the fix. Request inclusion or a correction on the review site, contribute a genuinely useful answer to the forum thread (disclosing who you are), and note which pages on your own site should answer the same question more directly.
- "Best [category] software for [audience] in [year]"
- "Top alternatives to [main rival]"
- "[Your brand] vs [main rival] for [use case]"
- "Is [your brand] worth it?"
- "How do I [job your product does] without [common pain]?"
Re-run the same set two to four weeks after a fix lands and compare the domain counts like for like. A prompt tracking tool keeps the questions fixed for you, and a citation sources view does the tallying.
How Perplexity differs from ChatGPT
It helps to know what you are looking at. Perplexity and ChatGPT reach an answer in different ways, and that changes how you should read each one.
- Search-first versus model-first. Perplexity searches the live web on almost every query and summarizes what it finds. ChatGPT leans more on what the underlying model already learned, reaching for the web only when it decides it needs to. So Perplexity mirrors the current state of the open web more directly.
- Speed of change. Because it is grounded in fresh search, Perplexity moves faster with your web footprint. Earn a mention on a page it already cites and you can sometimes appear within days. Influence in ChatGPT builds more slowly and is harder to attribute to a single page.
- Visibility of the why. Perplexity hands you the sources; ChatGPT often does not. That is why it is the better place to diagnose a problem, then confirm whether the fix carried across to the other engines.
None of this makes Perplexity more important than ChatGPT, which by most public estimates has a far larger user base. It makes Perplexity the better teacher. Diagnose in Perplexity, then check whether the change reaches ChatGPT. Our companion guide on how to track brand visibility in ChatGPT covers the model-first side in detail.
How to win citations in Perplexity
The winning move follows directly from how the engine works. Perplexity cites the pages its search surfaces for a question, so the goal is simple to state: be present in the domains Perplexity already cites for your questions. You do not need to rank first in classic search; you need to appear on the handful of pages the engine reads before it writes its answer.
Do not fight to be the source. Get named on the sources the engine already trusts.
In practice that means a short, concrete workflow:
- List the cited domains. From your tracked prompts, pull the domains Perplexity cites most for the questions you care about. This is your target list, ranked by how often they win.
- Earn a place on them. Get included in the review roundups, comparison pages, listicles and forum threads on that list. A single mention on a page that Perplexity repeatedly cites can sometimes move your visibility more than weeks of work on your own site.
- Make your own pages quotable. For the domains you do control, write clear, factual, well structured pages that answer the question directly, since extractable prose is what these engines lift. An AI crawler check confirms the engines can actually reach and read them.
- Watch the daily line. Because Perplexity can be tracked daily, you get near-real-time feedback on whether a new mention moved the needle, so you can double down on what works.
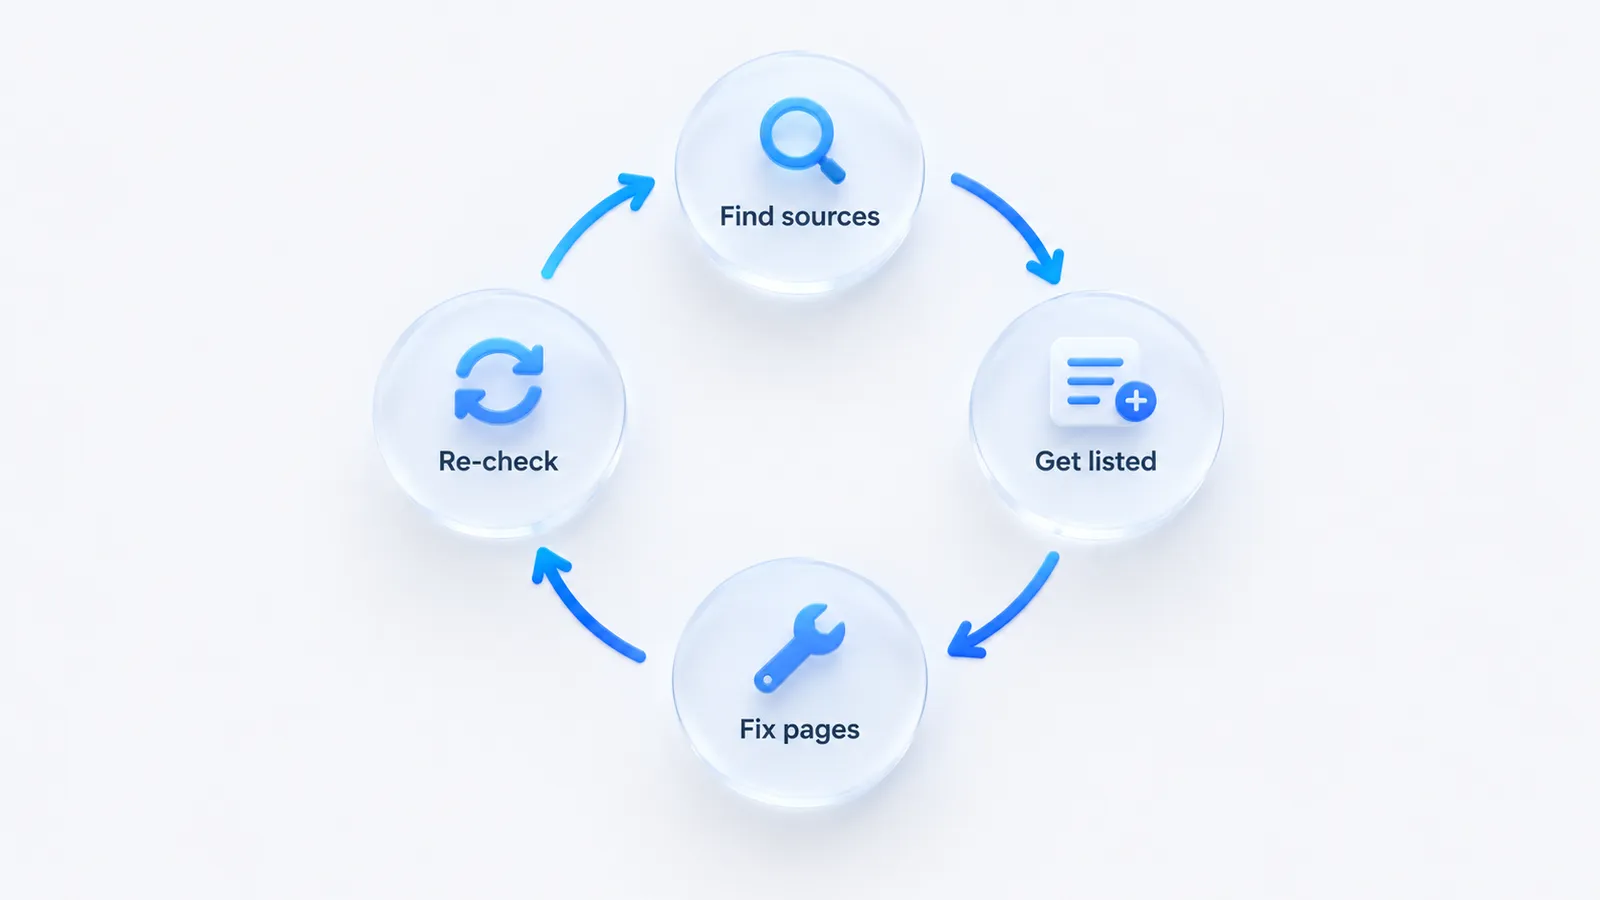
This is the core of AI search visibility and generative engine optimization work, and Perplexity is where the loop between action and result is tightest.
Putting it into practice
You can start by hand. Ask Perplexity your top ten buyer questions, write down whether you were named, and log the cited domains behind each answer in a spreadsheet. Repeat it weekly and you will see the pattern of who wins and where. The limit is time and consistency, since doing this properly across dozens of prompts, several phrasings each, and comparing week over week is more than a manual habit sustains.
That is the job a tracking tool does for you. Measure runs your buyers' questions across Perplexity, ChatGPT, Gemini, Claude and Google AI Overviews, scores your visibility, names the competitors that get cited instead of you, and shows the exact source pages winning each citation. Because it also pulls in Google Analytics 4, Search Console and Bing Webmaster data, your AI visibility sits next to the traffic it drives rather than in a separate silo. It is self-serve, starts at $19.99 a month, with no annual contract. You can start tracking or run the free AI visibility checker first. Either way, Perplexity is the best place to begin, because it is the one engine that shows you its work. When you are ready to compare tools, see our roundup of AI search visibility tools and the guides for Gemini and Claude.
Frequently asked questions
Why does Perplexity cite some sites and not others?
Perplexity runs a live web search and cites the pages it retrieves for the question, so the sites it cites most for your prompts are the ones to get listed on first.
Does Perplexity show which sources it cites?
Yes. Perplexity lists the web sources behind each answer inline, which makes it the most transparent major engine for understanding why a brand is or isn't recommended. Those cited domains are the pages you need to win to change the answer.
How is tracking Perplexity different from tracking ChatGPT?
Perplexity is search-first and cites live sources on nearly every answer, so its recommendations move faster with your web footprint. ChatGPT leans more on training data plus browsing. Perplexity is also the engine most tools can afford to run daily, so it is often the best early-warning signal.
We build Measure, a self-serve platform that tracks how AI engines describe and recommend brands, and connects that visibility to real traffic and revenue. Everything here is written from what we see in the data every day.