 measure
AI Search Visibility for SaaS: The 2026 Playbook
Your buyers ask AI assistants to shortlist tools before they ever visit your site. Here is how SaaS teams get on that shortlist.
- More SaaS evaluations now start with an AI-generated shortlist: buyers ask ChatGPT, Perplexity, Gemini or Claude for the best tool in a category before they visit a single vendor site.
- For software categories, engines lean on independent roundups, comparison and alternatives pages, review sites like G2 and Capterra, and your own product and pricing pages.
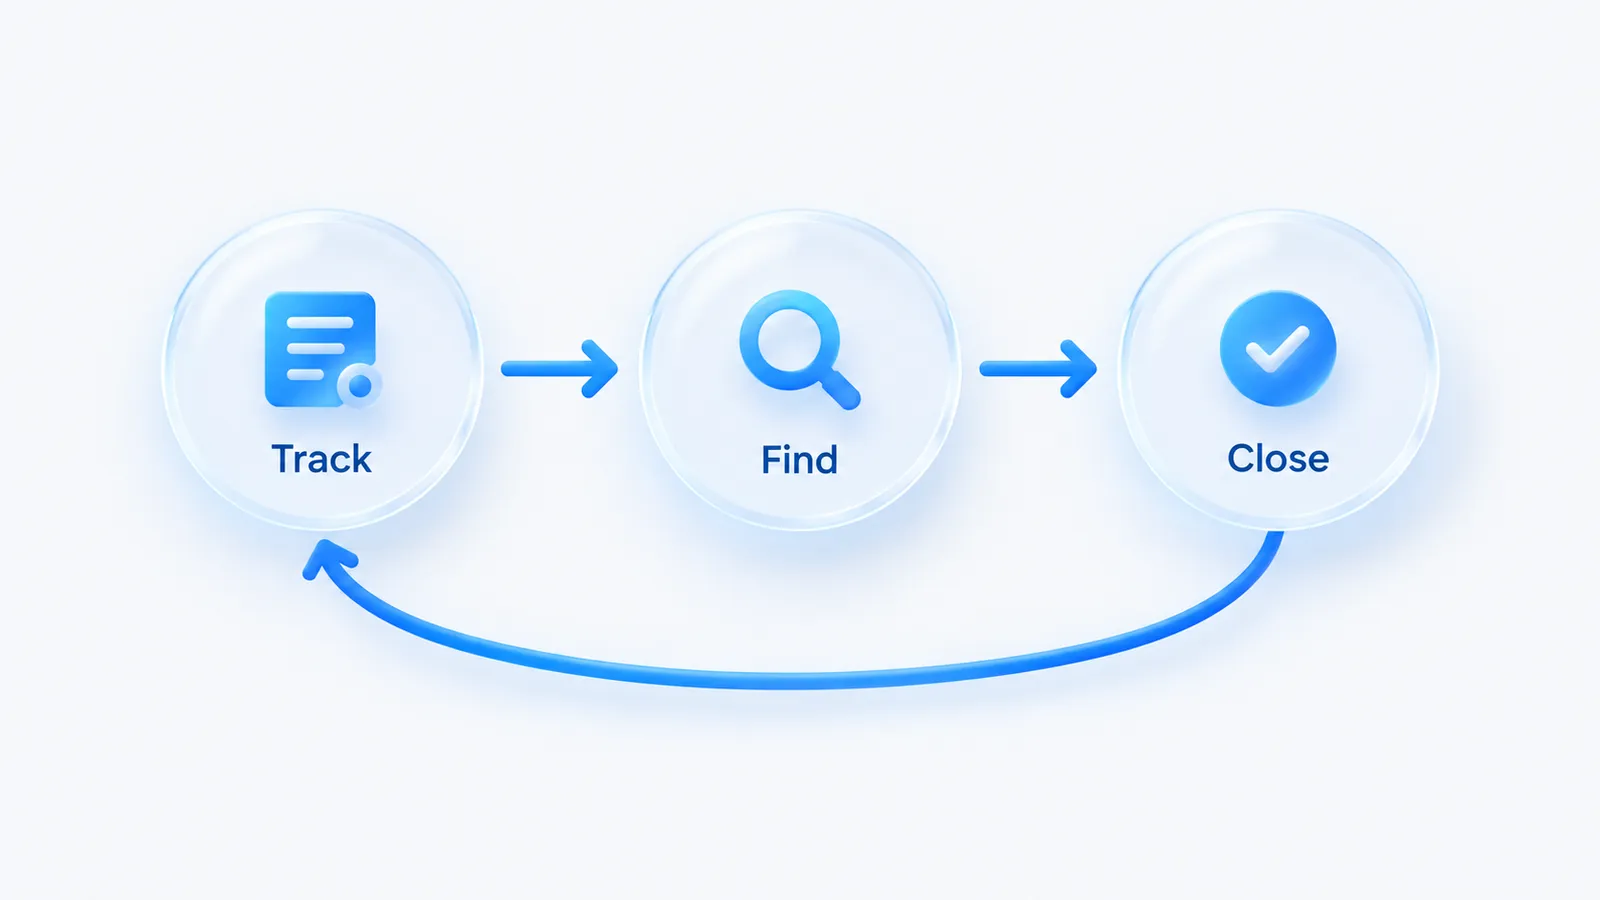
- The playbook is three moves: track your category, comparison and alternative prompts; find which sources win the citations you are missing; then close those gaps.
- The content that earns citations is unambiguous positioning, honest comparison pages, and pricing you can actually read on the page rather than hiding behind a demo form.
Why the shortlist moved into the model
Software has always been bought on recommendation. What changed is where the recommendation comes from. A buyer evaluating a category used to open five browser tabs: a Google search, a couple of roundup posts, a review site, maybe a Reddit thread. Now part of that first pass often happens inside an AI assistant (our AI search statistics page collects the sourced adoption figures). The buyer types "what is the best tool for X" or "alternatives to Y for a team of 20" and gets a synthesized answer that names a handful of products and cites some sources. By the time they land on a vendor site, the shortlist is already set.
For SaaS that is a sharper problem than for most categories, because the buying question is so explicitly comparative. Buyers ask assistants to compare project tools, pick a CRM for a small team, or list alternatives to the category leader. Those are exactly the prompts where being named or omitted decides whether you enter the evaluation at all. If your competitors show up in the answer and you do not, you may lose the deal before a demo is booked, and your funnel never records the loss because the buyer never arrived.
Traditional rank tracking cannot see any of this. It watches ten blue links; an AI answer is prose with no ranked page to sit in. Closing that blind spot is what answer engine optimization is about, and it is why AI search visibility has become its own discipline for SaaS marketing teams rather than a footnote to SEO.
Where engines look for SaaS answers
You cannot influence a citation you do not understand. When an engine assembles a shortlist for a software category, it is not inventing names from a vacuum. It is synthesizing from sources it has crawled and trusts, and for SaaS those sources cluster into four recognizable buckets.
- Independent roundups and "best tool" lists. The listicles that rank for "best [category] software" are cited heavily because they read as pre-digested comparisons. Being present, and positioned well, in the roundups that engines actually pull from is one of the highest-leverage things you can do.
- Comparison and alternatives pages. "X vs Y" and "alternatives to Z" pages, whether published by third parties or by vendors themselves, map cleanly onto the comparative prompts buyers ask. Engines lift them because the structure matches the question.
- Review platforms. G2, Capterra, TrustRadius and their peers aggregate structured, recent, user-generated signal about who serves which segment. They carry weight precisely because they are not the vendor talking about itself.
- Your own product and pricing pages. When an engine wants to confirm what a product does, who it is for, and what it costs, it reads the source of truth. A vague homepage and a pricing page gated behind "contact sales" give the model nothing concrete to quote, so it quotes a competitor instead.
Three of those four buckets are places you do not fully control, and the fourth is entirely yours. The work splits accordingly: earn a fair place in the sources you influence, and make the pages you own so clear that an engine can quote them without guessing.
The playbook: track, find, close
The temptation is to jump straight to writing content. Resist it. You cannot fix what you have not measured, and the fastest way to waste a quarter is to optimize for prompts your buyers never ask. Run the loop in order.
1. Track the prompts that actually decide deals
Build a prompt set from the real questions a buyer asks on the way to a purchase, not a keyword list. For SaaS those questions fall into three families that map directly to intent:
- Category prompts. "Best [category] software for [segment]," "top tools for [job to be done]." These decide whether you make the initial shortlist at all.
- Comparison prompts. "[You] vs [competitor]," "how does [you] compare to [incumbent] for [use case]." These decide who wins the head-to-head once you are in the running.
- Alternative prompts. "Alternatives to [incumbent]," "cheaper option than [big competitor]." These are pure switching demand, and being the named alternative to a category leader is some of the most valuable real estate there is.
Run each of those across the engines that matter and record, per prompt and per engine, whether you are named, where in the answer, and who is named instead. One phrasing under-samples because answers vary between runs, so use several phrasings of each question and aggregate. Engine-specific quirks are covered in our guides to ChatGPT and Claude; Claude in particular is used heavily by technical buyers, which matters for developer tools.
2. Find the sources winning the citations you are missing
A blank on a prompt is the start of the analysis, not the end. For every answer where a competitor appears and you do not, capture the sources the engine cited to build it. Patterns emerge fast: the same three roundups feeding a category answer, a specific G2 category page anchoring the review signal, a comparison post you have never heard of driving the alternatives prompt. Those cited domains are your target list, because they are the documents the model is retrieving. Understanding how LLM citations work turns a vague "improve our AI presence" into a concrete, addressable set of pages.
3. Close the gaps, then watch the trend
Now the work is specific. If a roundup that engines cite omits you, that is an outreach or a pitch. If a review category is thin, that is a campaign to gather recent reviews from happy customers. If the comparison prompt is won by a page that misrepresents you, publishing your own accurate comparison gives the engine a better source to quote. Then re-measure. A single scan is a snapshot; the trend over weeks is what tells you whether a move worked or was noise.
Worked example: turning a gap into a fix list
Take a hypothetical project-management tool for architecture firms, a small vendor competing with two general-purpose incumbents. The team tracks twelve prompts. A first read might look like this (illustrative, not real data):
- Category, "best project management software for architects": named in some runs, usually last. Cited sources: two vertical roundups and a review-site category page.
- Comparison, "[tool] vs [incumbent A]": named, but the answer says the tool lacks time tracking, which it shipped months ago. Cited source: a year-old third-party comparison.
- Alternatives, "alternatives to [incumbent B] for design studios": absent. Cited sources: a generic alternatives list that never mentions vertical tools.
Which fix each gap calls for
- Named but described wrongly: fix your own pages first (changelog, feature page, pricing), then ask the outdated source for a correction. This is usually the cheapest win.
- Named but ranked low: you are in the sources but weakly. Recent reviews and a clearer positioning line for the segment tend to help.
- Absent, and the cited sources omit you: that is outreach to the specific roundups, plus your own honest alternatives page so engines have at least one source that connects you to the query.
- Absent, and the cited sources include you: the engine is not reading you as relevant to that phrasing. Check that your pages use the buyer's words, not only your internal product terms.
Ranking the fixes this way keeps the quarter focused on gaps you can actually close, in order of cost, rather than producing content for its own sake.
The content moves that earn citations
Beyond chasing third-party sources, three changes to pages you own do more for SaaS citations than almost anything else, because they give the model unambiguous material to lift.
- State your positioning in plain language. An engine answering "best tool for [segment]" needs to know, in a sentence, who you are for and what you do. Marketing abstractions like "unlock your potential" are unquotable. "Measure is a self-serve AI search visibility platform for B2B SaaS teams" is quotable. Put the plain version high on the page.
- Publish honest comparison and alternatives pages. These map one-to-one onto the comparison and alternative prompts buyers ask, and a fair, specific page that concedes where a rival is stronger is more likely to be trusted and cited than a page that pretends you win everything. This is also how you influence the exact prompts you cannot control on third-party sites.
- Make pricing readable on the page. When a buyer asks an assistant what a tool costs, the model can only answer from what it can read. Structured, public pricing gets quoted; "contact us for a quote" gets skipped, and the engine reaches for a competitor whose numbers it can see. If your model allows any transparency at all, show it.
If an engine cannot quote your page, it will often quote a competitor whose page it can.
None of this is a trick to game the model. It is the same clarity a human buyer wants, written so a machine can extract it. That overlap is why the teams that do this well tend to improve human conversion at the same time.
Where a tool fits, honestly
You can run this loop by hand for a handful of prompts. Most SaaS teams find that it stops scaling around the point where they want dozens of prompts tracked across five engines, with source and competitor breakdowns, on a schedule, tied back to whether any of it moved traffic. That is the job Measure was built for, and to be upfront, this is our product, so weigh the specifics rather than taking the framing on trust.
Measure tracks your category, comparison and alternative prompts across ChatGPT, Perplexity, Gemini, Claude and Google AI Overviews, scores your visibility, names the competitors engines cite instead of you, and surfaces the exact sources winning each citation, which is the "find" step above done for you. Its distinctive piece is native attribution: it pulls Google Analytics 4 AI-referral traffic, Search Console and Bing Webmaster data so AI visibility sits next to the traffic it drives rather than in a separate dashboard. Agent M, the in-app assistant, will answer questions about your data and run a live scan or a page audit on request. It is self-serve with public monthly pricing, and the free AI visibility checker gives a one-off read before you commit to anything. To check that AI crawlers can reach your pricing and docs pages at all, run the AI crawler checker. If you would rather see the whole field first, the roundup of AI search visibility tools compares the alternatives, and if you run several brands, the agency playbook covers the multi-workspace version of all this.
The bottom line for SaaS
Your buyers are asking an AI to build their shortlist, and the model is quietly deciding whether you are on it based on sources you have never audited. The response is not mysterious. Track the category, comparison and alternative prompts that decide your deals; find the sources winning the citations you are missing; and close the gaps with clear positioning, honest comparison pages, and pricing a machine can actually read. Start with a small prompt set this week and measure it, then use the AI search ROI method to show whether the work moved pipeline.
Frequently asked questions
What should a SaaS team do if an AI engine describes its product inaccurately?
Fix your own pages first (feature page, changelog, pricing), then ask the outdated third-party source for a correction, and re-measure over several weeks.
Why does AI search visibility matter for SaaS?
Because software buying now starts with an AI-generated shortlist. When a buyer asks an assistant for the best tool in your category, the brands it names get the demo requests. If you are absent from that answer you are absent from the shortlist, no matter how you rank in classic search.
How do SaaS companies get recommended by AI engines?
By being well represented in the sources engines cite for your category: independent roundups, comparison pages, review sites like G2, and your own clearly structured product and pricing pages. Tracking which sources win the citation tells you exactly where to invest.
We build Measure, a self-serve platform that tracks how AI engines describe and recommend brands, and connects that visibility to real traffic and revenue. Everything here is written from what we see in the data every day.