 measure
AI Search Visibility for Ecommerce & Retail Brands (2026)
Shoppers now ask AI assistants what to buy. Here is how retail and DTC brands find out whether the answer is them.
- Shoppers increasingly ask ChatGPT, Perplexity, Gemini, Claude and Google AI Overviews what to buy, and the answer names a short list of products before anyone visits a store.
- AI engines build those recommendations by synthesizing reviews, retailer pages, comparison articles and marketplace data, so your product either makes the shortlist or it does not exist.
- Amazon's Rufus does the same job inside Amazon, recommending products from listings and review content on the largest retail search surface there is.
- Winning means being well represented in the sources engines trust, earning strong reviews, and publishing structured product content, then tying the mentions you earn back to orders and revenue.
Shoppers now ask an assistant what to buy
The path to a purchase used to run through a search box and a page of blue links. For some shoppers, part of it now runs through a conversation. A shopper asks an AI assistant for the best running shoe for flat feet, the best espresso machine under three hundred dollars, or a good alternative to a brand they already know, and the assistant answers with a short list of specific products and a few reasons for each. That answer shapes the decision before the shopper has opened a single retailer's site. If your product is named, you win consideration for free. If it is not, you are invisible at the exact moment intent is highest.
For retail and DTC brands this is a distinct problem from classic ecommerce SEO. Rank trackers watch the ten-result page. AI answers are synthesized prose with no page to rank in, so the old tools cannot see whether you appear at all. Measuring AI search visibility means running the questions your shoppers actually ask across the engines that answer them, recording whether your products get named, and tracking that over time so you can act on the trend rather than guess.
How AI engines decide which products to recommend
An assistant does not have a personal opinion about your product. It assembles a recommendation from the content it can find and trust, then writes it up in plain language. For retail queries that content comes from four main places, and understanding them tells you where the work is.
- Reviews and ratings. Editorial reviews, roundups and user ratings carry heavy weight, because they read as independent judgment. A product with many strong, specific reviews is easy for a model to justify recommending.
- Retailer and brand pages. Your own product pages, plus the big retailers that carry you, supply the specifications, price and availability the model quotes. Thin or inconsistent product data makes you harder to cite confidently.
- Comparison and buying-guide content. The best-of and versus articles that rank for category terms are prime training and retrieval fodder. Being present in the guides that define your category is one of the strongest signals you can send.
- Marketplace and structured data. Marketplace listings, structured product markup and aggregated pricing feeds give models the machine-readable facts they lean on when they need to be precise.
The practical takeaway is that AI recommendations are downstream of your presence across the wider web, not just your own site. You influence them the way you influence a good journalist writing a roundup: by being genuinely well regarded in the sources that journalist reads.
Amazon Rufus recommends inside the store
The pattern is not confined to general assistants. Amazon's Rufus is a shopping assistant built into the Amazon app and site, and it answers the same kind of buying questions right at the point of sale. A shopper can ask Rufus what to consider when buying a tent, or which of two products is better for a specific use. Amazon describes Rufus as drawing on its catalog, customer reviews and community questions, alongside information from the wider web. Amazon has not published how it weighs those inputs, so treat the listing advice below as sensible practice rather than a known ranking formula.
For anyone selling on Amazon, that makes listing quality an AI-visibility lever, not just a conversion lever. The same assets that help a human shopper decide also feed Rufus: a complete and accurate title, structured bullet points, thorough A-plus content, populated attributes, and a deep, healthy review base. A sparse listing with weak reviews gives Rufus little to work with when it narrows a category to a few suggestions. Treat your Amazon detail pages as source material an assistant reads.
General engines and Rufus reward the same underlying thing: clear, credible, well-reviewed product content. Work on the substance once and it pays off on both surfaces, rather than chasing each engine with a separate trick.
Track visibility at the product level
Brand-level tracking answers whether an engine has heard of you. Retail decisions happen one product at a time, so the useful unit is the product, or the product against a specific need. Build your tracked question set from the way shoppers actually phrase intent, which tends to fall into a few repeatable shapes.
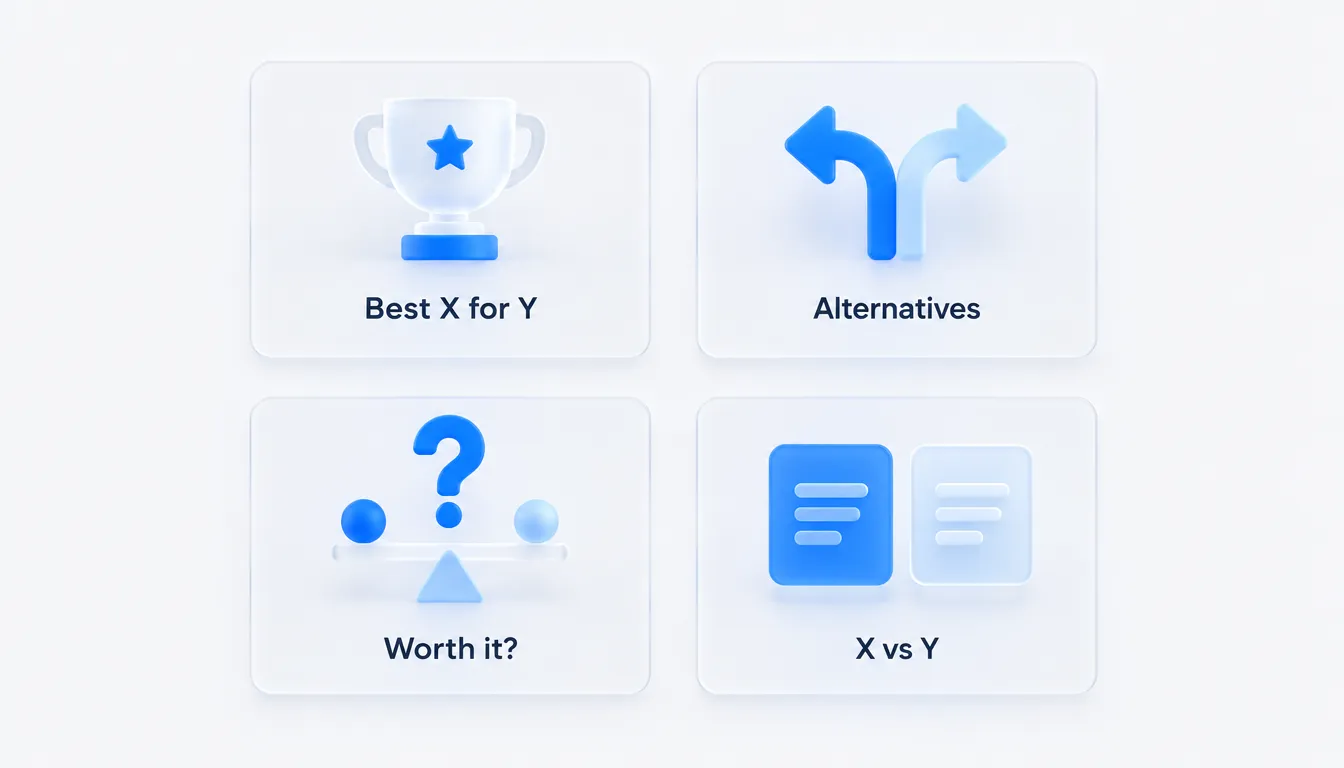
- Best X for Y. The category plus a constraint: best moisturizer for sensitive skin, best office chair for tall people, best budget road bike. These are the highest-intent recommendation queries and the ones you most want to be named in.
- X alternatives. Shoppers who know one brand and want options. If a competitor owns the category name, the alternatives query is where you can still get onto the list.
- Is X worth it. Validation queries about a specific product, including yours. The answer here is assembled almost entirely from reviews and sentiment, so it tells you how your reputation reads to a model.
- Comparison queries. Your product versus a named rival. These reveal exactly which attributes the engine credits to each side, which is a direct brief for your content and merchandising.
Run each question across the engines on a schedule and record whether the product is named, in what position, and which sources the answer cites. Ask any tool you evaluate how often each engine is actually checked, because sampling frequency usually differs by engine and by plan. Per-engine guides cover the details for ChatGPT, Perplexity and Gemini, and Google's own surface is covered in our AI Overviews entry.
Worked example: a product-level prompt set for one SKU
Take a hypothetical DTC brand selling a mid-priced home espresso machine, competing with two better-known brands. Brand-level tracking would ask whether engines know the brand. Product-level tracking builds a small set around the one machine:
- Best X for Y: "best espresso machine for beginners under $500", "best espresso machine for a small kitchen"
- Alternatives: "alternatives to [leading brand model]", "cheaper machine like [leading brand model]"
- Worth it: "is [your model] worth it", "[your model] problems"
- Comparison: "[your model] vs [rival model]"
Eight to ten questions, each with a couple of phrasings, is enough to see a pattern. Read the results as a diagnosis, because each query shape fails for a different reason:
What a loss on each shape usually means
- Missing from "best X for Y": you are probably absent from the buying guides the answer cites. Check the cited sources and work on getting fairly included.
- Missing from "alternatives": engines may not connect your product to the leader's category. State the comparison plainly on your own product page and comparison content.
- Negative "worth it" answers: the problem is reputation, not visibility. Read which complaints are repeated and fix the product, support or listing copy behind them.
- Losing "X vs Y": note which attributes the engine credits to the rival. If they are wrong, your spec data is unclear or inconsistent across retailers; if they are right, that is merchandising feedback.
Before chasing outside sources, confirm each tracked SKU page has: a title naming the product type and key spec, a specification table, current price and availability, a short FAQ answering the "worth it" objections, visible reviews, and valid Product markup. These are the facts an engine needs to cite you without guessing.
How to win the recommendation
Once you know which questions you lose and which sources win them instead, the work is concrete. Three moves do most of the heavy lifting for retail brands.
- Be present in the category sources engines trust. Identify the roundups, buying guides and review sites the answers keep citing, and earn a fair place in them through outreach, samples, accurate data and, where relevant, retail-media placement. If the guides that define your category never mention you, the engines rarely will either. This is the retail face of answer engine optimization.
- Earn strong, specific reviews. Volume and recency of credible reviews are likely among the bigger inputs to a product recommendation, though no engine publishes its weighting. Make it easy for satisfied customers to review, respond to criticism, and keep your review base healthy across your own site, the retailers you sell through, and Amazon.
- Publish structured product content. Complete titles, clear specifications, comparison tables, FAQs and valid product markup give models unambiguous facts to quote. Ambiguity is the enemy: if an engine cannot confirm a detail cleanly, it tends to recommend the product it can.
Progress shows up as a rising share of the recommendation answers in your category that name your products, which is your AI share of voice against the specific rivals you compete with, which the competitor share of voice view tracks per engine.
Tie AI mentions to orders and revenue
A visibility score is a means, not an end. For a retail brand the question a founder or a finance lead will ask is simple: did being recommended sell more product? Answering it means connecting the mentions you earn to the traffic and orders that follow, rather than leaving the two in separate dashboards.
That link comes from your analytics. AI assistants send some referral traffic, and that traffic lands on your product and category pages before it converts. It is often a small share of sessions today, and some AI influence never shows up as a click at all, so read it as a lower bound. Native attribution pulls Google Analytics 4 AI-referral sessions, Search Console and Bing Webmaster data alongside your visibility trend, so you can watch AI-sourced visits, add-to-carts and orders move as your share of recommendations rises. When a competitor launches a campaign and starts winning the best-of queries, you see it in the visibility trend and, a little later, in the revenue.
Measure (our product) is built for this loop: it tracks the engines above and includes AI traffic attribution from GA4, Search Console and Bing Webmaster data, so visibility sits next to the sessions and orders it drives. A small brand running on a handful of SKUs can start on the entry plan, or with the free AI visibility checker for a one-off read. Google's own reporting is covered in our guide to the Search Console generative AI report. For the full method of connecting AI visibility to money, see how to measure AI search ROI, and if you want a fast first read on where you stand, the free AI visibility checker gives you a one-off snapshot before you commit to tracking.
The bottom line
Retail buying has quietly moved part of the way into the answer box, and it is spreading into the store itself through assistants like Rufus. The products that get recommended tend to be the ones that are well reviewed, well documented and well represented in the sources answers are built from. Start by measuring which of your buyers' questions you already win and lose, per product and per engine, then work the sources and prove the payoff in orders.
Frequently asked questions
Should ecommerce brands track AI visibility per product or per brand?
Per product. Recommendation answers name specific products, so build a small prompt set for each key SKU covering best-for, alternatives, worth-it and versus questions.
How do AI engines recommend products to shoppers?
They synthesize an answer from reviews, retailer pages, comparison content and marketplace data, then name specific products or brands. Amazon's Rufus does this inside Amazon using product listings and reviews. Winning means being well represented in the sources each engine trusts for your category.
Can I track product-level AI visibility?
Yes. You track the buying questions shoppers ask (best X for Y, X alternatives, is X worth it) across engines and record whether your products are named. For Amazon specifically, tracking Rufus's answers to category and comparison questions shows where you stand inside the marketplace.
We build Measure, a self-serve platform that tracks how AI engines describe and recommend brands, and connects that visibility to real traffic and revenue. Everything here is written from what we see in the data every day.